Used by 100+ students in 10+ countries and counting
See what Learnica handles, and what it leaves with you.
A two minute film. It opens with the gap I watched appear in my own classroom, follows one class from the first question to the review page, and shows the evidence behind each design decision.
Learnica keeps upwhile you
Learnica captures the class and keeps the page moving, then asks you to predict, choose, or recall at a few useful moments. You get the ease of Otter or Granola while more of the thinking remains yours.
Start class
Start with the class you already have.
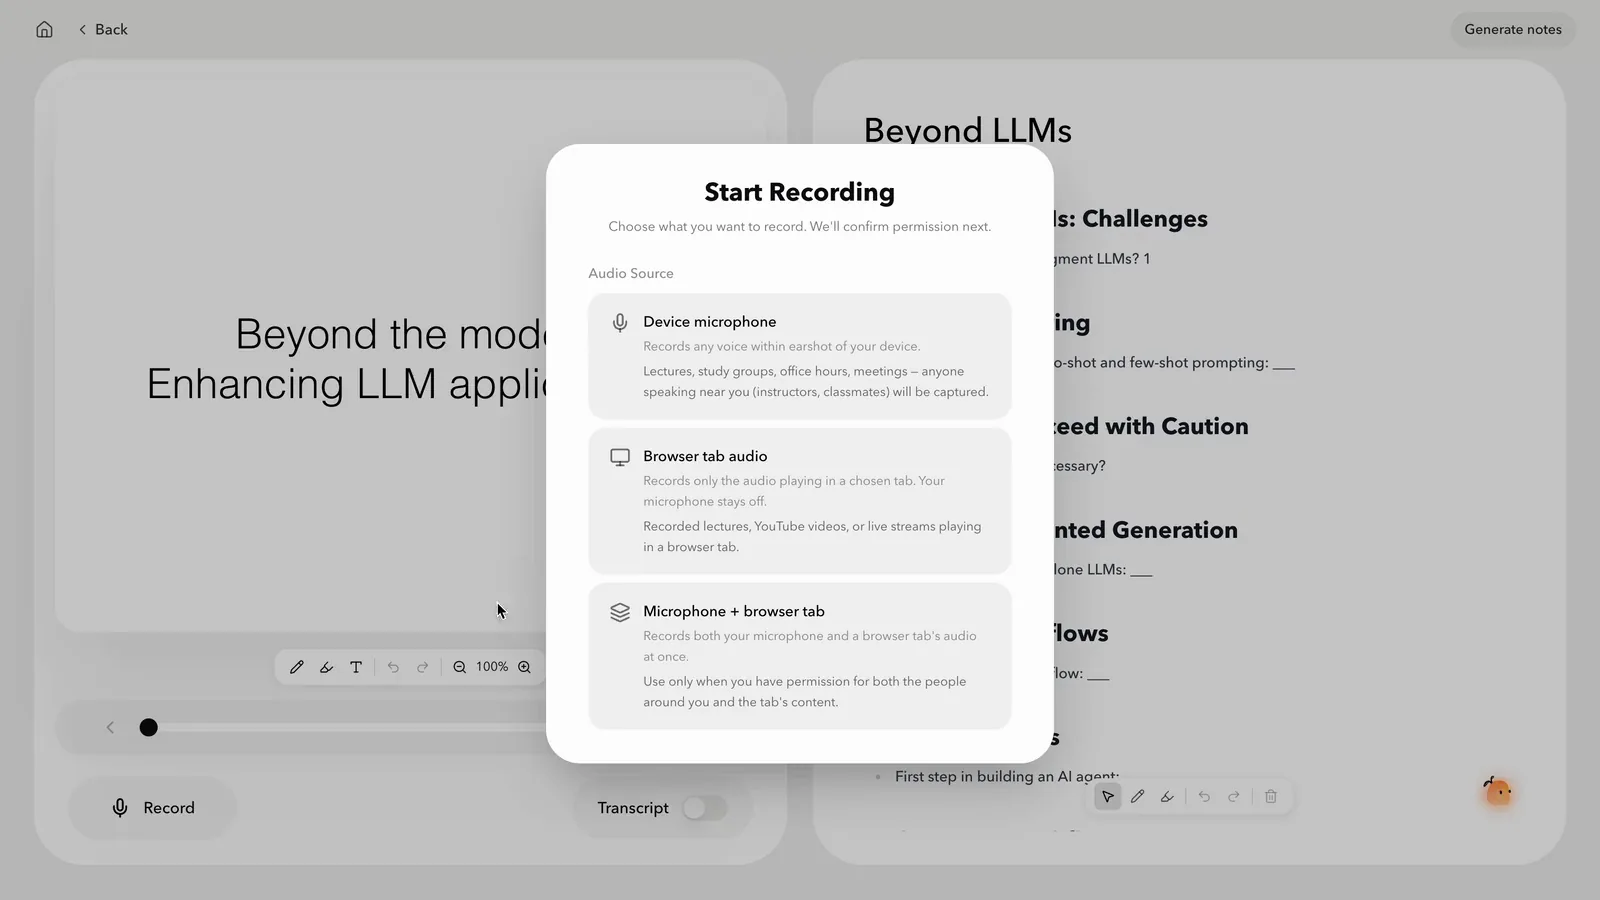
Choose the microphone for a live room, the browser tab for a lecture playing elsewhere such as Coursera, or both at once. A YouTube link opens inside Learnica the same way. Every path lands in the same live workspace.
Before class
Give the lesson somewhere to land.
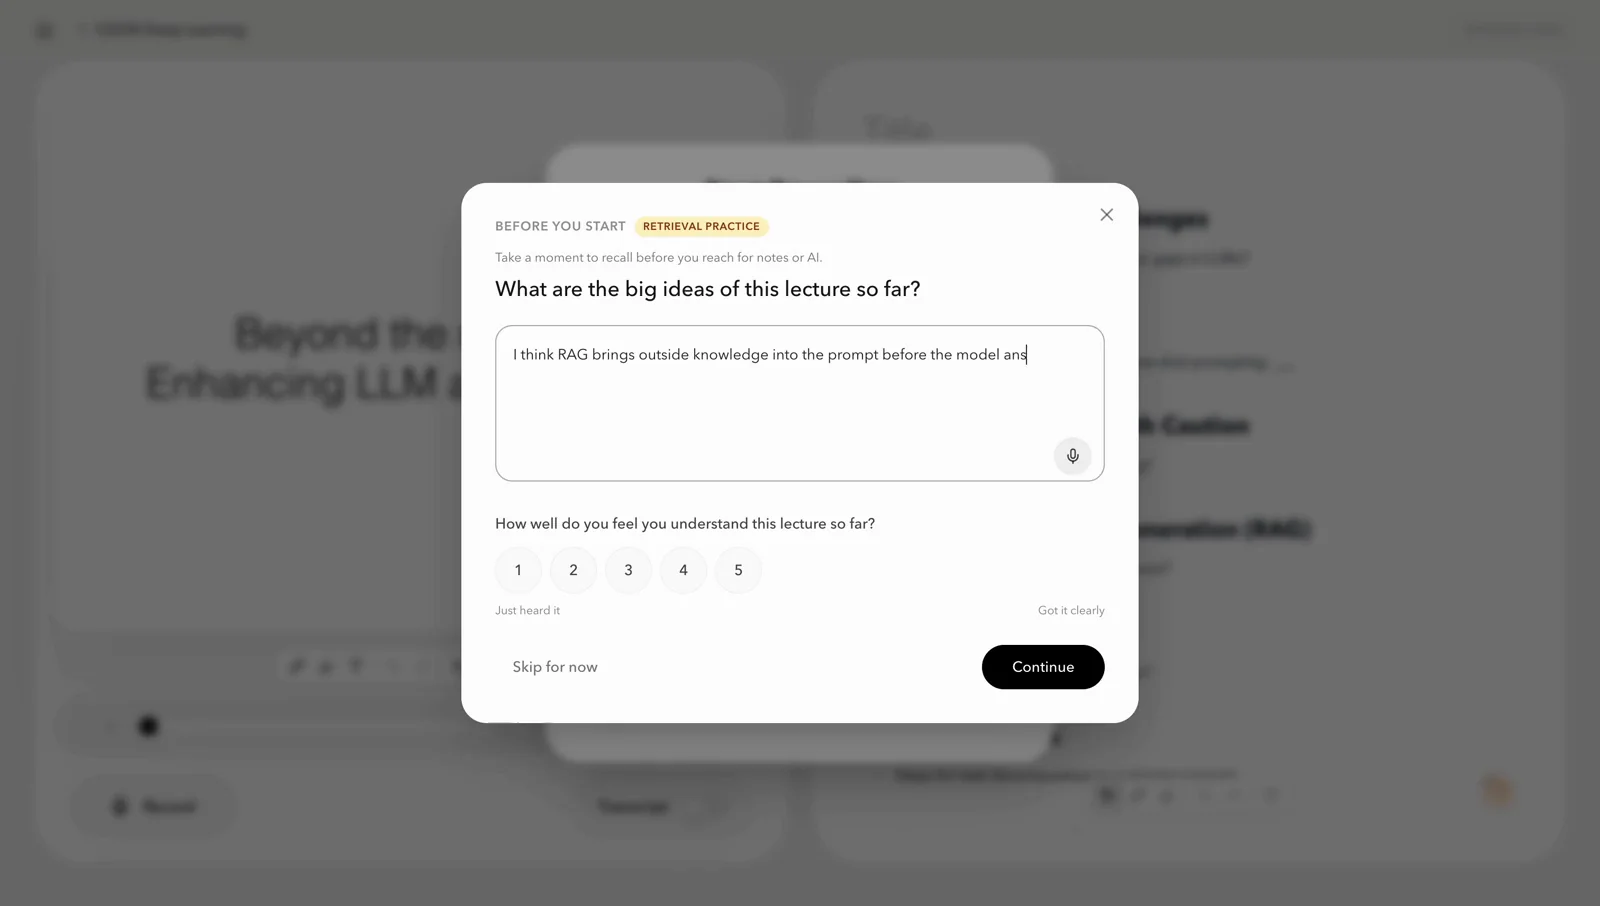
Learnica asks for a quick prediction before class begins. The question is optional, but answering it gives the coming explanation something to connect to.
In class
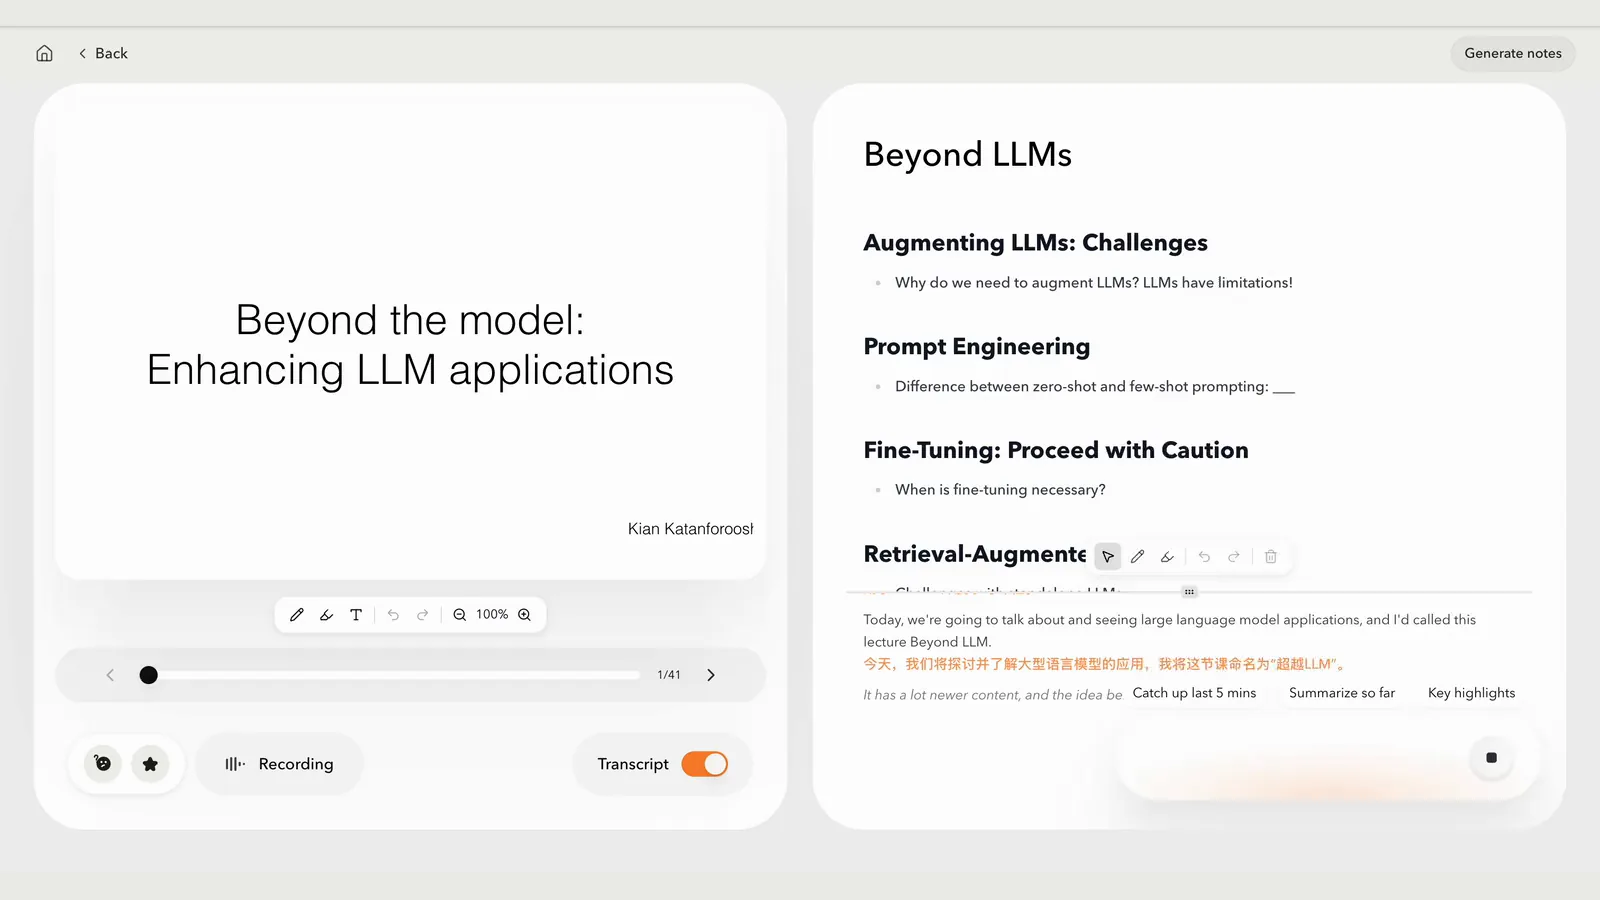
Let the recording keep up.
Live captions, translation, and a complete transcript catch the words you miss. The page stays as flexible as GoodNotes or Notability without making you chase every sentence.
While notes generate
Turn the wait into a memory check.
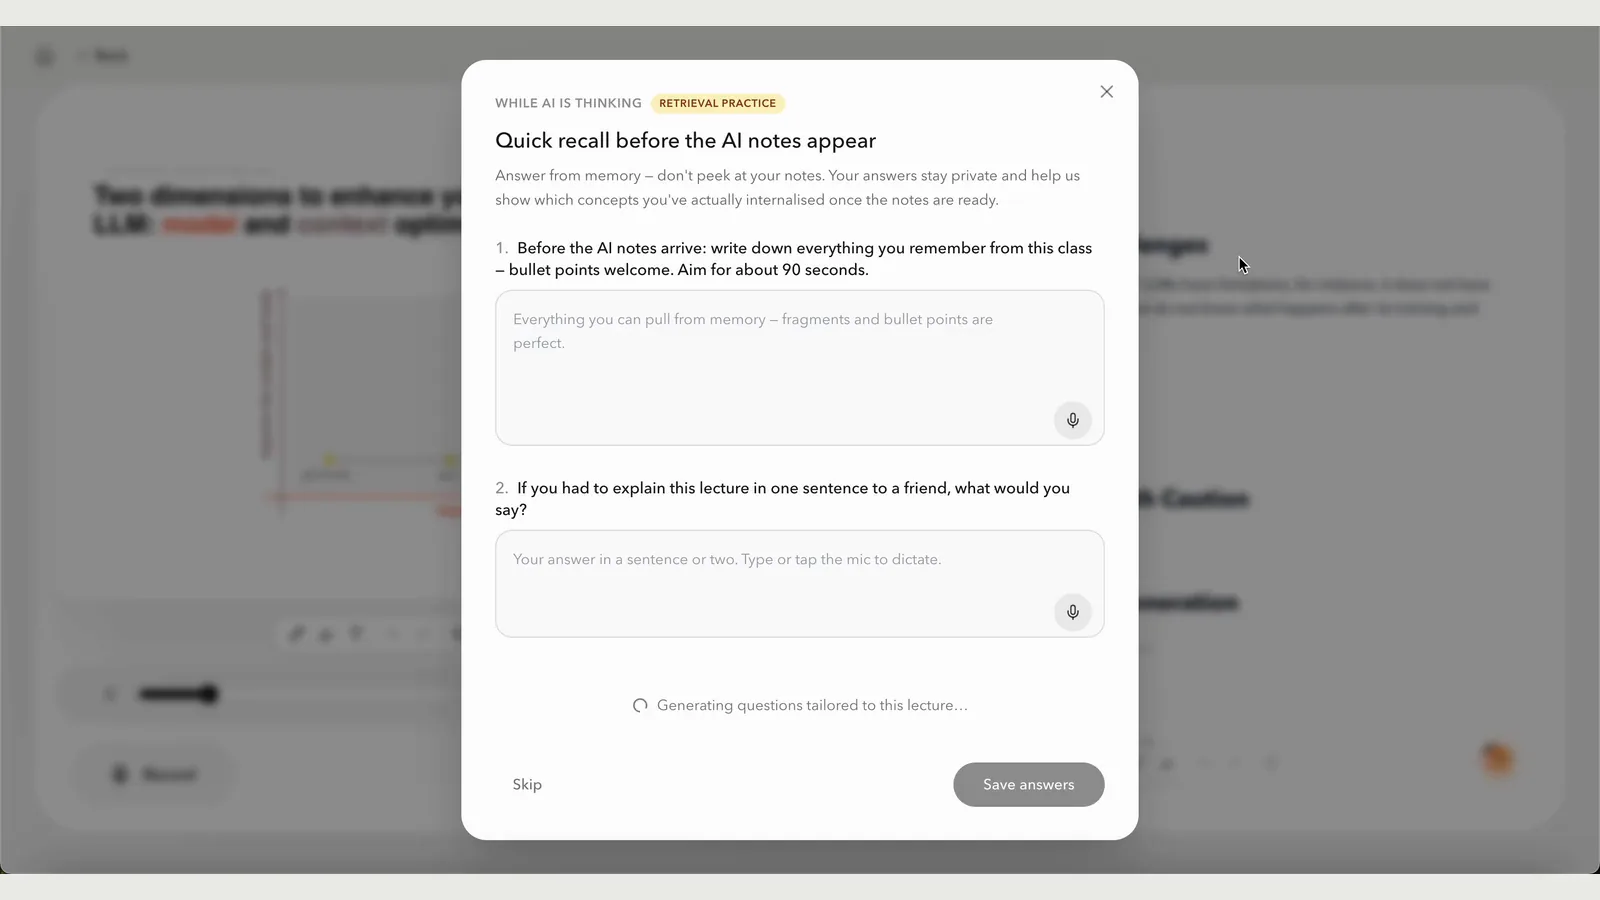
Every AI note taker needs a moment to turn a recording into notes. Learnica uses that same pause to ask what you can recall before the finished page opens.
After class
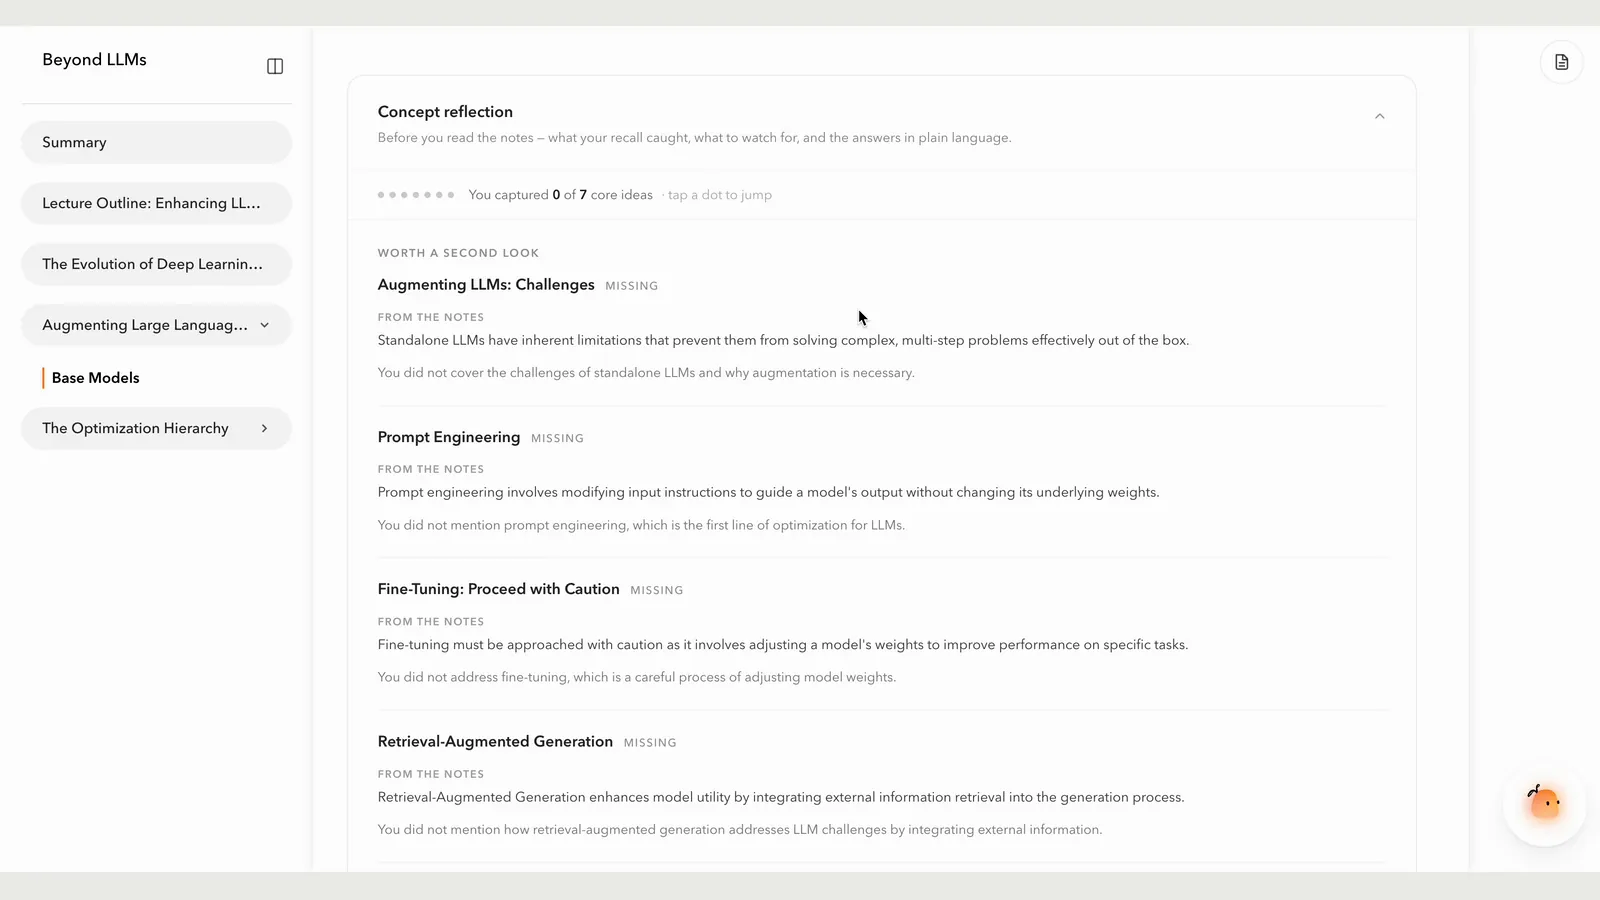
See what stayed with you.
The concept mirror compares your recall with what the class covered and points to what needs another look. Otter, Granola, and Notion AI show what was said, while Learnica also shows what reached your own words.
In class
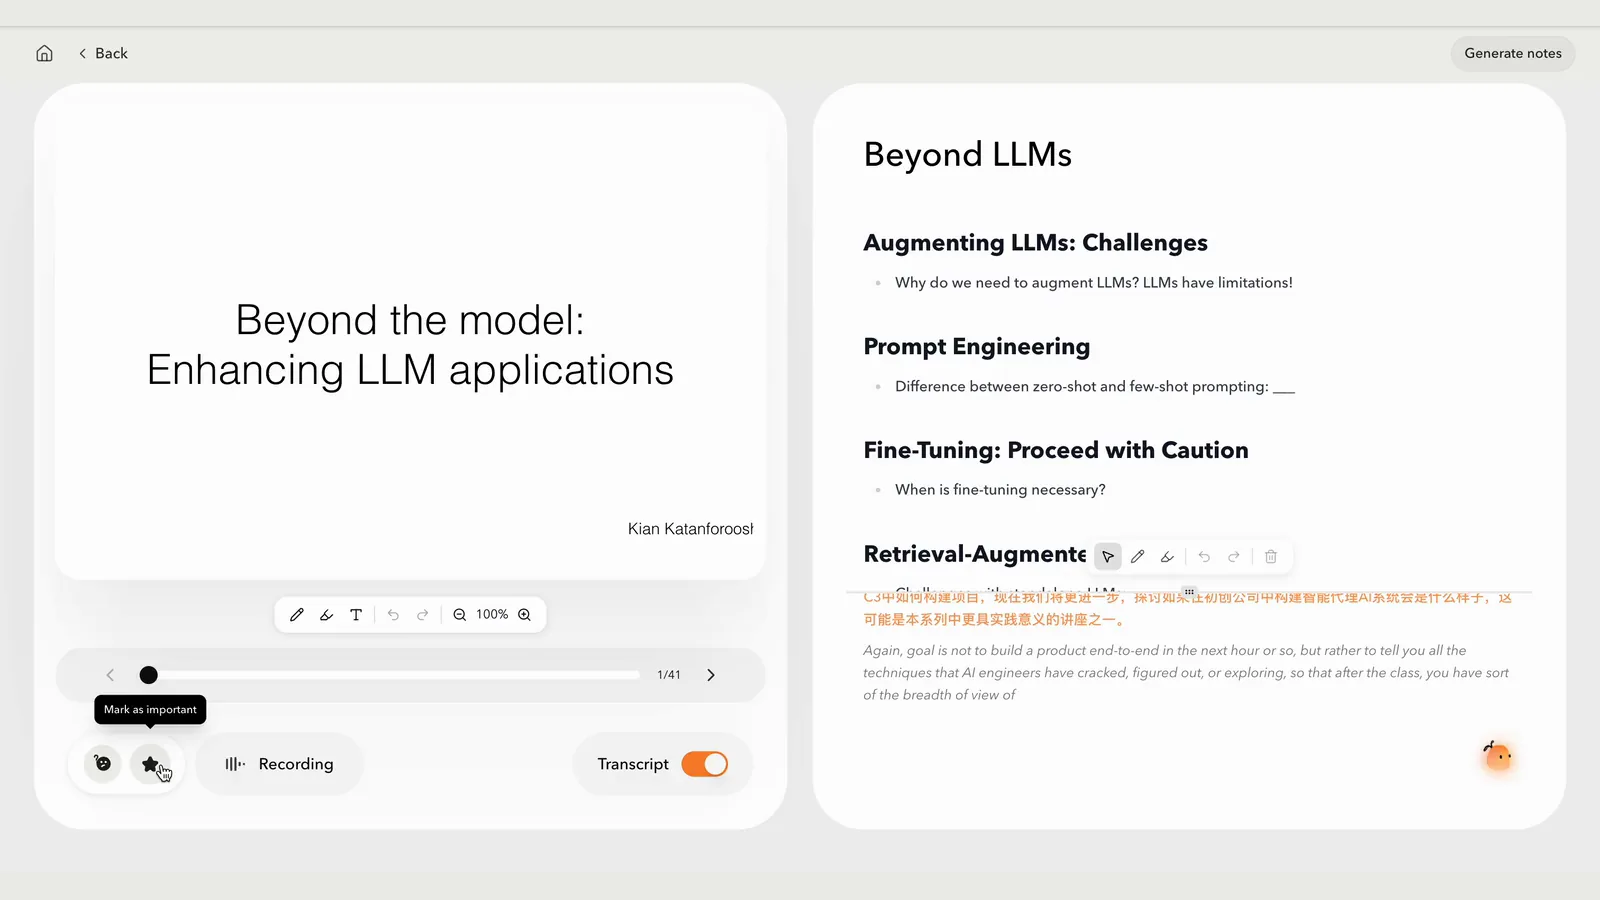
Flag the moment, not the whole lecture.
One tap marks a passage as important or as something you did not follow. The yellow and purple markers stay on the heading, so review starts where you actually struggled.
Any time
An assistant that asks before it answers.
The assistant works from the class record and from your own notes. It opens with a question or the smallest useful hint, and it gives the full explanation once you have made an attempt.
The gate
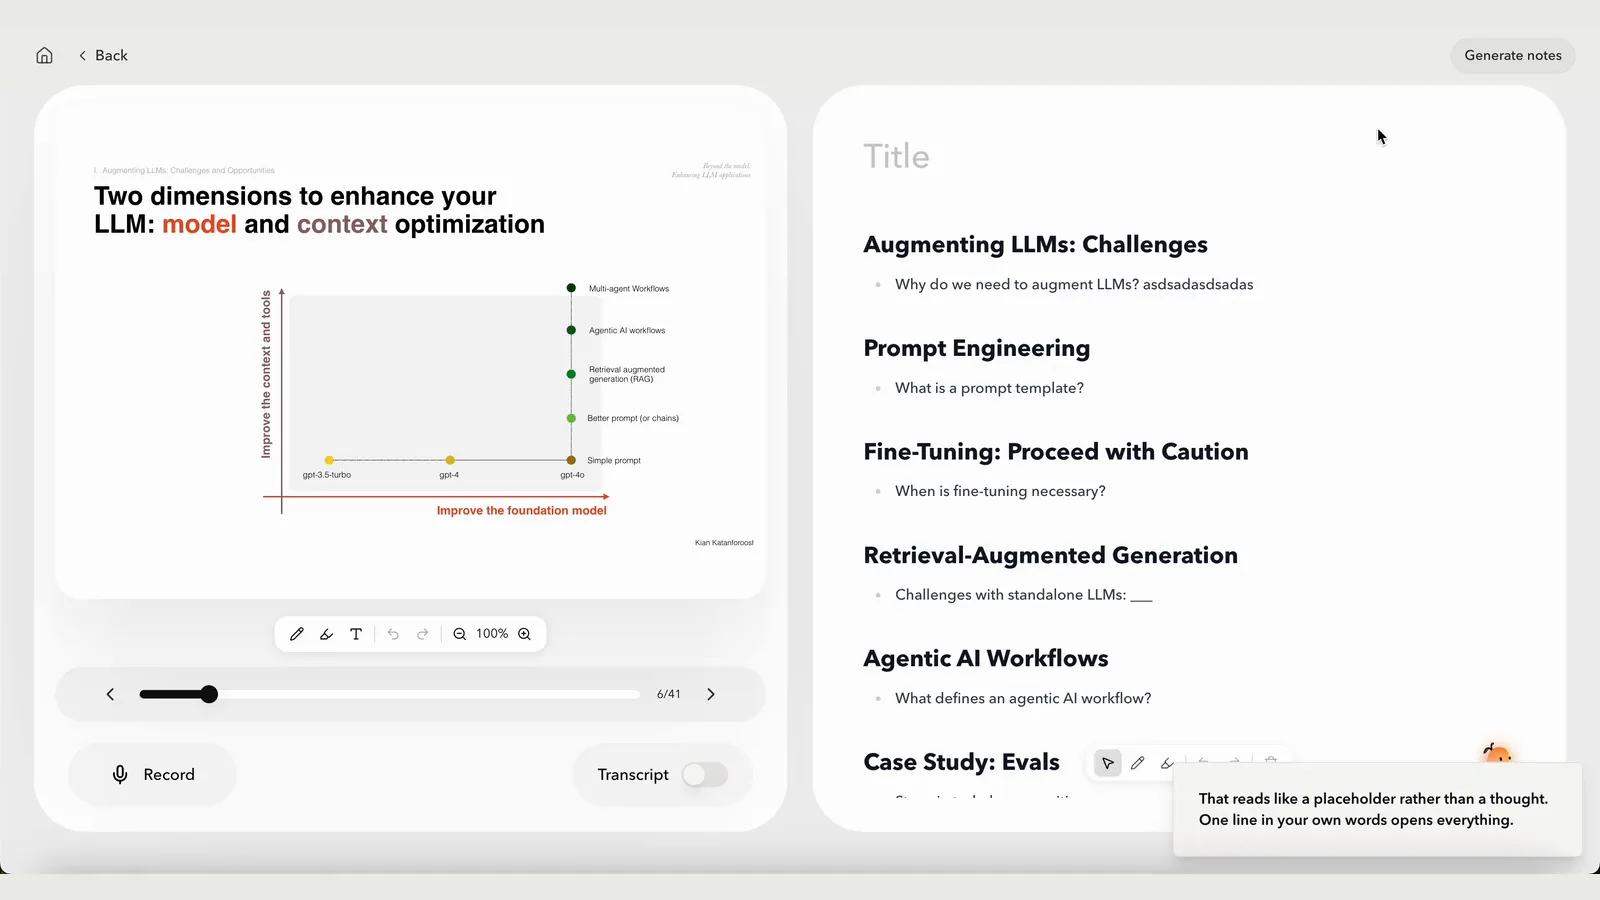
Help opens after a real attempt.
A line of your own, a stroke, or a captured slide opens the assistant and the notes. Learnica also asks for a minute of class and a few words of your own, so an empty keystroke is not mistaken for thinking.
Keep the effort that changes what a student can do later.
The same task can help one learner and overwhelm another. Learnica treats support as a hypothesis, then looks past the finished page to unaided recall, transfer, and calibration.
Useful difficulty is not a fixed amount of friction.
It depends on what the learner already knows, what the task asks, and what must still be possible when the tool is gone.
productive struggle
Protect the work that creates meaning.
Prediction, selection, retrieval, and self-explanation ask the learner to construct or recover an idea, so Learnica keeps those moves in the flow.
Predict before an explanation
Choose and rephrase the main idea
Recall before reopening the notes
Explain why an answer works
wasteful struggle
Take on the work that spends attention without teaching.
Racing to transcribe, recovering lost audio, and decoding a second language can consume capacity without strengthening the target idea, so Learnica carries that load.
Race to transcribe every sentence
Decode a second language in real time
Recover audio lost to a short interruption
Copy the same material again after class
These are design judgments, not permanent labels. The assistance dilemma is deciding when support removes waste and when it removes the thinking that produces learning. Prior knowledge, timing, scaffolding, fading, and expertise reversal can change that answer. Learnica tests each change against delayed unaided recall, transfer, metacognitive calibration, and the learner's experience instead of treating a cleaner artifact as proof of learning.
Four moments turn that learning contract into product behavior.
Each one has a plain interaction at the surface and a testable mechanism underneath.
Before class
Try an answer before you see one.
A quick guess gives the coming explanation somewhere to land, even when the guess is wrong.
View evidence
Pretesting asks learners to attempt retrieval before content. It improves later memory with an effect of d=1.1 at 95% error (Richland, Kornell and Kao 2009).
While taking notes
Give the page shape without filling it in.
Headings and prompts remove the fear of a blank page while leaving the meaning for the student to build.
View evidence
Encoding improves when learners select, organize, integrate, and self-explain. In cognitive load terms, the skeleton removes transcription burden while protecting germane load. Guided outlines outperform complete notes at d≈0.55. A scaffold should fade as knowledge grows because of expertise reversal (Larwin and Larwin 2013, Kalyuga 2007).
Before notes open
Ask memory before opening the notes.
Bringing an idea back strengthens it in a way that reading the same idea again does not.
View evidence
Retrieval practice produces a testing effect of g=0.50 across 61 studies (Rowland 2014). Learnica places the attempt inside the generation wait, so it does not add another waiting step.
During review
Compare memory with evidence.
A clear mirror helps students separate an idea they understood from one they only remember seeing.
View evidence
Metacognitive calibration is part of self-regulated learning and is weak without external evidence. Unaided judgment tracks actual learning at roughly γ≈0.27 (Koriat and Bjork 2005), so Learnica scores the student's own recall against a concept list committed before generation.
Learning-performance distinction
The artifact is not the outcome.
A finished note can look better while learning gets worse. The product therefore separates performance with help from what remains when the help is gone.
Delayed recallPrimary outcome
What can the learner bring back after a week has passed and the finished notes are closed? Every lecture in the study ends there, with an inference test one week later.
Sample inference item · one week laterA clinic wants answers grounded in this week's guidelines. Why would retrieval serve it better than fine-tuning?
With support
Can the learner stay oriented and make a useful attempt without spending the class racing to copy?
Transfer
Can the learner use the idea in a new question rather than repeat the wording that appeared in class?
Calibration
Does confidence track what the learner can actually explain, and does the concept mirror improve that judgment?
What happens when the AI does more?
Two studies make the same tradeoff visible. A polished result can improve while the learner becomes less able to work without the tool.
Figure 01Post-test score
Moderate help beat complete automation.
Intermediate AI13.88
Fully automated AI10.28
Students liked the fully automated notes most, but the intermediate condition produced the stronger post-test score.Chen et al., 2025 · N=30, p=.002
Figure 02Relative change in performance
Hints protected the exam while improving practice.
The standard tutor produced +48/−17 across practice and exam. The hints-only tutor produced +127/0.Bastani et al., 2025 · nearly 1,000 students
Four ways to leave class with notes.
The page can look complete in all four. The difference is who had to keep up and whether the learning process is visible afterward.
Analog
Pen and paper
Who keeps up
You
What the page keeps
Only what you write
When thinking happens
Throughout class
What review shows
Your notes
Digital handwriting
GoodNotes and Notability
Who keeps up
You
What the page keeps
Your writing and the media you add
When thinking happens
Throughout class
What review shows
Your notebook and linked media
Automated notes
Otter, Granola, and Notion AI
Who keeps up
The AI
What the page keeps
A transcript or polished summary
When thinking happens
Whenever you choose
What review shows
The record and summary
Learnica
Complete capture with your thinking
Who keeps up
The AI
What the page keeps
The class and your own attempts
When thinking happens
At small moments in the flow
What review shows
The record and what stayed
A classroom AI system has to earn every answer.
A fluent response is the easy part. The system has to survive the room, retrieve the right evidence, release only the help the learning moment allows, and show where it came from. Learnica separates capture, evidence, policy, generation, and evaluation so one polished answer cannot hide a broken source or a missing learning step.
See one question move from thought to answer.
The live product captures the class, shapes notes from class materials, and compares recall. The next build adds a tool-using tutor that releases help in stages.
Start with a prediction.
Learnica asks the learner to commit to one idea before the lecture. The answer stays locked, while capture and translation remain available.
Why can adding more context make an answer worse?
✓Before class2 of 3
✓Preview the question
Write one prediction
Join the lecture
More context can bury the passages that matter, so the model may follow the wrong evidence.
Your own words
Today, help waits for a thought of your own. The planned engagement check will look for meaningful language rather than count characters.
The machine keeps pace while the learner decides what matters.
Complete captions and translation follow the room while the note stays short enough to belong to the student.
Live transcriptRunning now
A capable model can still answer badly when the context is weak.
Retrieval first finds relevant passages, then adds them to the prompt as evidence.
More context is not automatically better. Retrieval and generation need separate evaluation.
StreamStateRecord
MicrophoneLiveLocal copy
TranscriptShapingComplete sentences
TranslationFollowingBounded window
Retrieval before generation
RAG lets a model look things up before answering, but the retrieved context still has to be relevant.
Quiet assistance
Matching your note to the lecture sources
Smallest useful hint
You may want to add why context precision matters.
Keep the learner's words in view.
Learnica keeps the learner's shorthand visible beside additions grounded in class sources. The next provenance layer will make the source of each addition directly inspectable.
my-note.md+3-1
1-RAG lets a model look things up.
1+Retrieval finds passages before generation.
2+The passages become evidence in the prompt. [1][2]
3+Retrieval and generation need separate evaluation. [3]
A longer context can still fail when the useful evidence is difficult to find.1Lecture transcript at 18:422RAG question answering diagram on slide 123Component and end-to-end evaluation on slide 28
Lecture transcript18:42
Course deckSlides 12 and 28
Diagram inside the note
QuestionRetrieveAnswer
Generating a retrieval map
Use the class before using the web.
The tutor retrieves and verifies course evidence first, then chooses the smallest useful response.
Why can more context make a RAG answer worse, and how would I test it?Course sources first
Evidence trace
Matched the question to the transcript at 18:42 and the RAG diagram on slide 12.
Retrieved the component and end-to-end evaluation framework from slide 28.
Course evidence was sufficient, so web search did not run.
AnswerGrounded in class
A longer context can contain more evidence and still hurt an answer when relevant passages are harder to identify. Test retrieval and generation separately, then evaluate the final response.1RAG question answering diagram on slide 122Evaluation framework on slide 28
The system proves itself when the room stops behaving like a demo.
One trace follows a live class through an audio failure. The other follows a request for help through the planned tutoring policy.
Running today
A headset dies in the middle of a sentence.
A student may switch devices, lose a headset, or pass through a short network interruption while the lecturer keeps speaking.
A reconnection, second by second
+00:00The headset stream drops mid-sentence.
+00:02Unsent audio chunks are held in IndexedDB on the device.
+00:09Capture resumes on the new source, inside the same session.
+00:11Captions and translation rejoin at the sentence boundary.
What the student seesThe class continues through a short interruption without discarding the buffered passage.
A learner asks for help before making an attempt.
The policy chooses a learning move before any answer is drafted, so orchestration does not quietly become answer generation.
Attempt checkedThe learner's own words come first.
Move chosenRecall, question, or hint fits the moment.
Evidence gatheredThe transcript, deck, and course memory stay in scope.
Claim verifiedSources and release policy must agree, or release stops.
What the student seesThe learner gets the next useful move, not a finished solution.
What students can use todayWhat the next build adds
Live capture
A messy room still becomes a readable record.
Learnica keeps streaming when an audio source changes or the network drops briefly, then returns captions as complete sentences with translation moving beside the lecture.
A stable capture graph resumes after device changes. Audio chunks persist in IndexedDB before upload, while sentence-boundary processing and bounded translation windows keep multi-hour sessions responsive.
Engagement gate
The unlock will recognize a real attempt.
The current gate asks for a thought of the student's own before AI help becomes available. The next version will check for meaningful engagement rather than count characters.
Trivial keystrokes are not the design intent. The planned check asks whether the entry is in the student's own words without turning the gate into surveillance or a writing test.
Class-scoped generation
The class remains the boundary.
The deck, transcript, and concept list define what generated notes may cover. The student's own words remain distinct from the generated record, and the source material stays available for review.
Retrieval-augmented generation is scoped to the current class before synthesis. The next provenance layer will attach stable source identifiers to generated additions. The concept mirror already compares recall against a target committed before generation rather than a list invented after the answer is known.
Policy-bound tutor
Use an agent only when the next learning move is genuinely uncertain.
Capture, gates, and release remain deterministic. Planning begins only when the learner's attempt, the available evidence, and the help policy leave more than one valid next move.
A typed state machine owns the session. Planner, retriever, coach, and verifier receive bounded roles and schemas. Course uploads and web results remain untrusted evidence, so retrieved instructions cannot redefine tool permissions. Tools run with least privilege. The interface exposes sources, tool outcomes, and release decisions rather than private chain of thought, while prompt injection tests remain part of the release evaluation.
Research controls
A missing condition never becomes a convenient guess.
Each student receives a server-held condition for each lecture. If that state is missing, the intervention stays closed rather than assigning a condition on the client.
The experiment path fails closed. Each effort feature reports telemetry against a declared success signal, and recall judgments require blind human validation at κ ≥ 0.61 with a reported confusion matrix before automated scores count as evidence.
Retrieval and memory
Deeper retrieval has to earn its delay and cost.
An exact course term should be found quickly. Semantic retrieval, reranking, graph traversal, or the open web enter only when the question needs them, and remembered claims stay visible to the learner.
Lexical retrieval comes first. Reciprocal-rank fusion and cross-encoder reranking enter when ambiguity justifies them, while graph traversal is reserved for questions that depend on relationships across classes. Web search runs only when course evidence is insufficient or freshness matters. Retrieval precision and recall, generation faithfulness and relevance, latency, cost, and end-to-end learning are evaluated separately. Course memory stays scoped to the learner and course, and remains inspectable, correctable, and deletable.
I kept thinking about the questions that came back blank.
Before Stanford, I taught more than 1,000 undergraduates across seven computer science courses. As generative AI coding assistants became part of everyday coursework, I sometimes saw elegant take-home code, and then, on an in-person final, a simple question we had practiced many times was answered wrongly, or came back blank. There was no need to assume cheating, because the work could be genuinely theirs while too much of the thinking still happened somewhere else.
At Stanford, I began treating that classroom question as both a learning-science problem and a product problem. I brought years of building full-stack AI systems at Apple, TikTok, Alibaba, AMD, and early-stage startups to a tool that now serves about 100 students. Learnica keeps the complete record of a class, follows the room with captions and translation, and creates a few well-timed opportunities to predict, choose, recall, and explain. The aim is to make a difficult class easier to enter, wherever a learner begins, without letting a polished artifact stand in for understanding.
Education becomes personal when a teacher notices the hesitation behind a polished page, remembers an earlier struggle, and stays long enough to help the idea land. Learnica can carry the record, keep the evidence close, and make more room for those moments. What it cannot do is care whether the idea finally lands, because that responsibility and that relationship must remain human.